Operations Practical
What a DDoS does to your server, and to your host
Two completely different attacks share one word, and only one of them can be filtered by somebody who is not reading your traffic. What your provider’s first move actually is when the packets arrive, why the industry default finishes the attack rather than stopping it, and the six things worth deciding beforehand.
17 min read Published 5 September 2026 Checked 1 month ago
Every hosting page on the internet promises DDoS protection, and almost none of them says which of the two attacks it is talking about. The distinction is not academic: one of them is arithmetic, is settled hundreds of kilometres away by somebody you will never speak to, and is genuinely included in the price. The other cannot be filtered by anyone who is not reading your traffic, and no provider can honestly sell it to you without saying so. Here is what actually happens to the packets, what your host is most likely to do next, and the part of it that is your problem no matter who you buy from.
Two attacks, one word, almost nothing in common
A denial-of-service attack has exactly one goal — to consume a resource until there is none left for anybody else — and the entire subject turns on which resource. That choice decides who is able to stop it, where, and at what cost. It is not a spectrum. There are two families, they are stopped by different parties using different equipment, and a provider that answers the question with a single number is answering about one of them and staying quiet about the other.
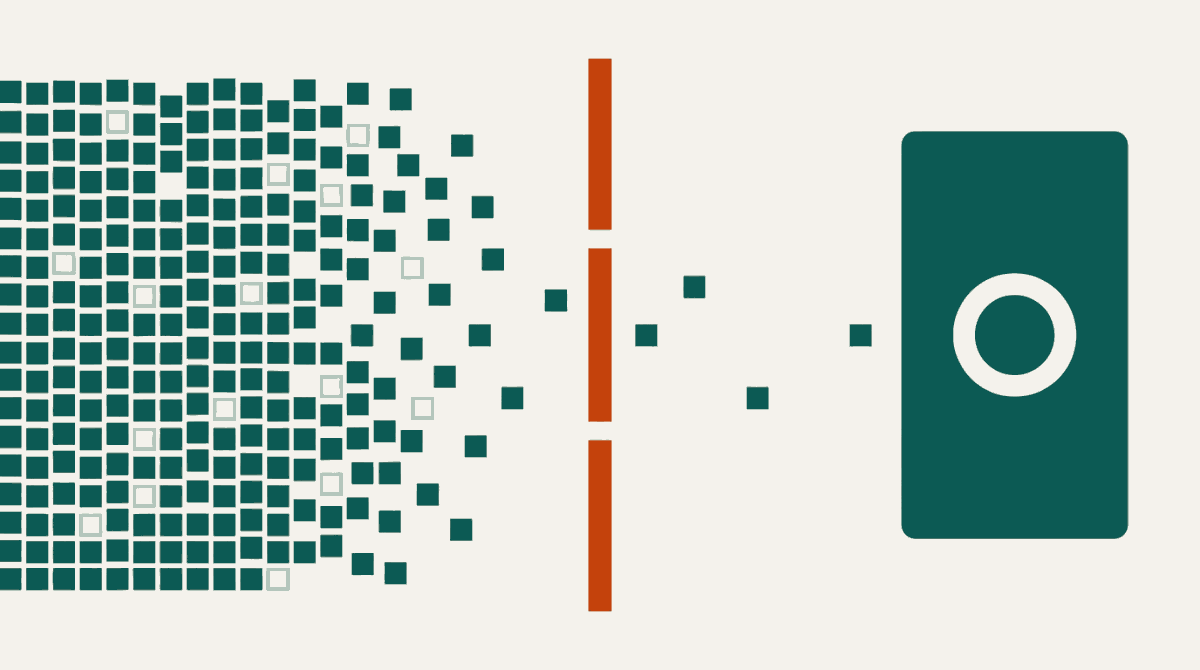
The first family attacks the pipe and the plumbing. Floods of UDP, floods of SYN packets, reflected traffic from misconfigured servers elsewhere on the internet. None of it cares what you run. It does not know whether you host a forum or a git mirror, it never reaches your application, and in most cases it never reaches your machine at all — it fills the link, or exhausts a table in a router, somewhere above you. Because it is indifferent to content, it can be recognised and dropped by somebody who cannot see inside your traffic. That is what makes it solvable upstream, and it is why this is the half that gets included for free.
The second family attacks your application. Requests that are individually perfect: correct TLS handshake, valid HTTP, a URL that exists. Your server is delighted to receive them. It is the database behind the search box, or the password hashing behind the login form, that falls over — and it falls over at a request rate your network graph will barely register. There is no signature to match, because there is nothing wrong with any single request. The only thing that distinguishes the flood from a good day is intent, and intent is not a field in a packet header.
| What arrives | Filtered upstream | Yours to fix | What it exhausts, and where it is actually stopped |
|---|---|---|---|
| Reflected UDP flood | Yes | No | Link capacity. The traffic is bulk, forged and indifferent to what you run, so it can be discarded by somebody who cannot see inside it — but only by capacity sitting above the link it was sent to fill. Nothing done at your provider’s edge, or on your machine, helps once that link is already full. |
| SYN flood | Yes | Partly | The connection state table, not the bandwidth. Half-open connections are cheap to send and expensive to remember. Filtered at the network edge, and largely defused on your own kernel: SYN cookies have shipped enabled on Linux for years and most people have never had to know. |
| Small-packet flood | Yes | No | The forwarding plane. Routers and network cards are sized in packets per second, and a flood of tiny packets is aimed at that number rather than at the bandwidth figure. Stopped upstream, in hardware. This is the one that ruins a firewall while the traffic graph still looks calm. |
| Slow-header and slow-body attacks | No | Yes | Worker slots. A few hundred connections, opened and then fed one byte at a time, hold a thread-per-connection server open until it has no threads left. Solved by timeouts and per-address connection limits in your reverse proxy; an event-driven front end absorbs it almost by accident. |
| HTTP request flood | No | Yes | Your CPU and your database. The expensive endpoint — search, login, cart, anything that writes — is the target, and a few thousand requests a second is enough. Stopped inside your application, or inside a proxy you have deliberately let decrypt your traffic. There is no third place. |
| Scraping and credential stuffing | No | Yes | Everything, slowly. Not an attack on availability at all, but it arrives looking exactly like one and gets reported as one about half the time. Stopped by your own rate limits, per endpoint and per account. Mitigation bought against the wrong diagnosis is the most expensive kind. |
The top three rows are your host’s job and the bottom three are yours, and no amount of money moves a row between the halves. When a provider says “DDoS protected”, the honest reading is that the top three are covered. That is worth having. It is not everything, and the gap is where almost every real outage happens.
The mitigation that finishes the job for the attacker
Now the part nobody puts on a product page. When a flood arrives at a network, the provider has two options. It can filter — separate the attack from your real traffic and keep you online, which costs capacity, equipment and somebody’s attention. Or it can announce your address to its upstream carriers with a tag that means discard everything addressed to this. That is a blackhole, also called a null route, and it is the industry default for a reason that has nothing to do with you.
The mechanism is standardised and completely public. RFC 7999, published by the IETF in October 2016, defines a well-known BGP community named BLACKHOLE, registered with IANA as 0xFFFF029A — the document notes drily that the low-order two octets in decimal are 666. Its semantics are one sentence long: the presence of the community is “an advisory qualification to drop any traffic being sent towards this prefix.” It can serve as the trigger in a remote-triggered blackhole configuration, the technique described in RFC 5635 back in 2009. Any competent network can do this in seconds, from a router, at no cost.
Read what it does. The flood stops arriving. The provider’s links recover. Every other customer on that network goes back to normal. And you are off the internet — not slow, not degraded, gone, as completely as if the machine had been unplugged, and for exactly as long as the provider leaves the announcement in place. The attacker’s goal was that your service should be unreachable. The mitigation achieved it, at zero further cost to them, and it will be described to you afterwards as a mitigation because from the network’s point of view that is precisely what it was.
The line to remember: a blackhole protects the provider from your attacker. It is a rational, standardised, entirely defensible operational decision — and its effect on you is indistinguishable from the attack succeeding.
Which means the question to ask is never “how many terabits”. It is: under what circumstances do you null-route a customer, do you call first, and how long do you leave it in place.
There are two tells, and both are readable before you spend anything. The first is the acceptable-use policy rather than the marketing page. Look for the clause about traffic “directed at” your service, and for the words at our sole discretion, may suspend or may null-route. That paragraph, not the shield icon on the homepage, is the provider’s actual DDoS policy, and it is binding.
The second is whether protection is sold as a tier. A “protected IP” for an extra monthly fee is a clear statement that the ordinary address is not protected, and there is only one thing a network does with an unprotected address under load. Filtering that is genuinely upstream costs the same whether it is defending one customer or all of them, which is why charging per address is a pricing decision rather than an engineering one. Our own position on this is that the filtering is on by default on every port with nothing to enable, and that we would rather telephone you than blackhole you — a promise that is only worth anything because it is falsifiable, and because the same page publishes the capacity figures it rests on.
The arithmetic upstream, and why packets beat bits
Volumetric attacks are not clever, and they do not require a botnet. They require servers that answer a small question with a large answer, and the internet is full of them. CISA publishes the table, with amplification factors measured per protocol: DNS returns 28 to 54 times what was asked of it, NTP 556.9 times, SSDP 30.8, CharGEN 358.8, CLDAP 56 to 70. Exposed memcached instances answer between 10,000 and 51,000 times over. Because UDP does not verify who sent the question, the answer goes to whatever address the attacker wrote on it — yours.
Run the multiplication once and the marketing stops making sense. A single machine on an ordinary gigabit uplink, pointed at enough exposed memcached servers, can direct terabits at a target. The attacker rents nothing and compromises nothing. This is why the only capacity figure that means anything is the one above your provider’s transit, not the one at their edge. If a host has 20 Gbps of transit and 20 Gbps of scrubbing hardware in their own rack, then 21 Gbps of flood congests the transit link and everybody behind it suffers — the filtering is real, correctly configured, and on the wrong side of the bottleneck. Filtering has to happen where there is still room for it, which means the carriers have to be doing it, which means your provider has to have arranged that in advance with people you will never meet.
The second piece of arithmetic is the one that catches experienced people out. Network equipment is sized in packets per second, not bits. One gigabit of 1,500-byte packets is about 81,000 packets a second, which is nothing. The same gigabit made of 64-byte packets is around 1.5 million packets a second — eighteen times the work, for identical bandwidth. A flood engineered against that number will flat-line a firewall, a virtual switch or a small router while the traffic graph you are staring at shows a modest bump and no reason for anything to be wrong. “We have ten gigabits” is therefore not an answer to any question worth asking.
This is also why always-on filtering and on-demand filtering are different products with the same name. On-demand means detect, then re-announce your prefix through a scrubbing provider, then tunnel the clean traffic back — realistically tens of seconds to several minutes before the first clean packet arrives. A great many attacks are shorter than that. Mitigation that reliably arrives after the event it was bought for is a subscription, not a defence, and the difference is invisible on both providers’ feature lists.
Filtering is not free, and the cost is latency. Traffic that is inspected on-path, in hardware, upstream of the link, costs well under a millisecond in normal conditions — we publish our own figure alongside the routes it is measured on. Traffic diverted to a scrubbing centre in another country and tunnelled back costs whatever that detour costs, permanently, whether or not anybody is attacking you. Both designs are legitimate. Only one of them is usually disclosed.
Layer 7, and the price of having it filtered
Everything above stops at the transport layer, and so does everything your provider can do for you without your permission. An HTTP request flood is inside your TLS session. Nobody upstream can see the URL, the method, the headers or the body — that is what the encryption is for, and it works. Your provider filtering it would require your provider to be decrypting it, and a provider who can decrypt your traffic has a capability that no jurisdiction argument, disk-encryption scheme or privacy policy survives.
So there are two honest options and no third one. Either you handle application-layer floods yourself, inside your own application, or you place a proxy in front that you have deliberately given your certificate and private key to, and it handles them by reading every request before passing it on. That is the trade, in one sentence, and any vendor promising layer-7 protection without one of those two things happening is describing layer-3 filtering in nicer words.
If you choose the proxy, the whole arrangement then rests on a single assumption: that the attacker cannot reach your server directly. The moment your origin address is known, every request goes around the proxy and the protection you are paying for is decorative. Origin addresses leak through DNS history for the name you used before you put the proxy up, through mail sent from the same machine, through certificate transparency logs that list every name you ever requested a certificate for, through the subdomain nobody remembered to proxy, and through internet-wide scanners that match your certificate against every address on the internet in a matter of hours. A proxy without a firewall that refuses everything except the proxy’s own address ranges is a layer you have added without removing anything — and the same guide covers what else that layer forwards on your behalf.
The unglamorous half of layer 7 is cheaper and works without a vendor. A cached response served to an anonymous visitor costs you almost nothing, so caching aggressively converts most of a flood into a non-event. Rate limits belong on the expensive endpoints rather than on the site as a whole, because the homepage was never the target. Anything slow enough to be worth attacking is usually worth optimising anyway. And a static fallback page — on a different address, saying plainly that the service is under attack and when to try again — is worth more to your users during the incident than any amount of infrastructure that fails silently.
What to decide before it happens, in order of value
None of this can be arranged during an attack, and all of it can be arranged in an afternoon. The ordering matters more than the completeness: the first two cost nothing and change the outcome more than the rest put together.
- Read the abuse clause before you buy (10 min). Find the paragraph about traffic directed at your service and read what the provider reserves the right to do. If it says they may null-route at their discretion with no obligation to notify you, then that is the product, whatever the product page says, and you now know it for free.
- Establish whether filtering is included or a tier (5 min). If it is an upsell, the default is a blackhole; ask what happens to an address on the ordinary plan while the attack is in progress, and how quickly the upgrade can be applied. “At the time of the attack” is not an answer, because BGP does not converge on your timetable.
- Split what must stay up from what may fall over (an afternoon). A static site and a status page on one address, the application on another. When the application is under a request flood, your users still reach something true instead of a timeout, and you keep a channel to tell them what is happening.
- Put a cache in front of everything anonymous (an afternoon). This is the single highest-value piece of application-layer defence available, it costs nothing per month, and it makes your service faster on the days nobody is attacking it — which is all of them but one.
- Rate-limit per endpoint, not per site (an hour). Login, search, registration, password reset, anything that writes to the database or sends mail. A global limit generous enough for a busy homepage is far too generous for a login form.
- Learn the escalation path, and use it once (20 min). Find out who is reachable at three in the morning, on what channel, and how they identify you. A ticket queue with a next-business-day target is not an escalation path; discovering that mid-incident is how a bad hour becomes a bad week.
Two of those six are decisions and four are configuration, and the two decisions are worth more than the four. Add a seventh if you are honest with yourself: settle in advance the point at which you would rather be blackholed for an hour than keep fighting. Some attacks are not winnable at your budget, and having chosen the moment beforehand is the difference between a decision and a panic.
Six questions for anyone selling “DDoS protection”
All six are answerable in writing, before money changes hands, by anyone who actually operates their own network. The willingness to answer is itself most of the finding.
- Is the filtering upstream of your transit, or at your edge? Any capacity at or below the transit figure protects the provider’s equipment, not the customer’s reachability. The two numbers have to be quoted together to mean anything.
- Under what circumstances do you null-route a customer, and do you call first? The only question on this list whose answer you cannot guess, and the one that decides what your bad day looks like.
- Is it included, or a tier? If tiered, ask what protects the untiered addresses in the meantime. There is precisely one answer, and it is the previous question.
- Always-on, or triggered — and what is the time to first clean packet? Anything measured in minutes is a defence against sustained campaigns only, which are the minority.
- What do you do about layer 7, given that you cannot read my TLS? The right answer is a version of “nothing, and here is who can, and here is how to lock your origin down so they matter.” Any answer that skips the constraint is worth reading twice.
- What did the last attack you handled look like? Size, duration, vector, what you did. A network that runs real traffic has stories; one that has never had an attack has no procedure either.
The answers tend to sort providers faster than any feature table, because five of the six are about operations rather than equipment, and equipment is the only part that can be bought on the day of the sales page. Ours are on the network page, with the capacity figures and the things we deliberately do not do to your traffic, and the constraint the layer-7 answer rests on is the same one that makes the rest of this site’s argument coherent: we cannot filter what we have promised not to read.
The last thing worth saying is a subtraction. A denial-of-service attack is one adversary among several, and for most small platforms it is not the first one to arrive — the ranked version of that list puts an automated scan, a copyright complaint and a payment dispute above it, and it is right to. Buy the filtering, because it comes with the port and costs you nothing. Spend the afternoon on the cache, the rate limits and the fallback page, because those are yours. And do not let a shield icon on a pricing page persuade you that the half of the problem that lives inside your own application has been taken care of by somebody else. It has not, and it will not be.
Written by the engineers who run the platform, and re-read 1 month ago. If something here is wrong or has gone out of date, say so from the panel — that is where about half of these came from.